07 / Blog · 17.10.2026
AI Needs a Job Status, Not a Loading Indicator
Generative AI rarely fits the classic request-and-response cycle. A robust background process makes runtime, errors, retries and human decisions visible – improving both architecture and user experience.
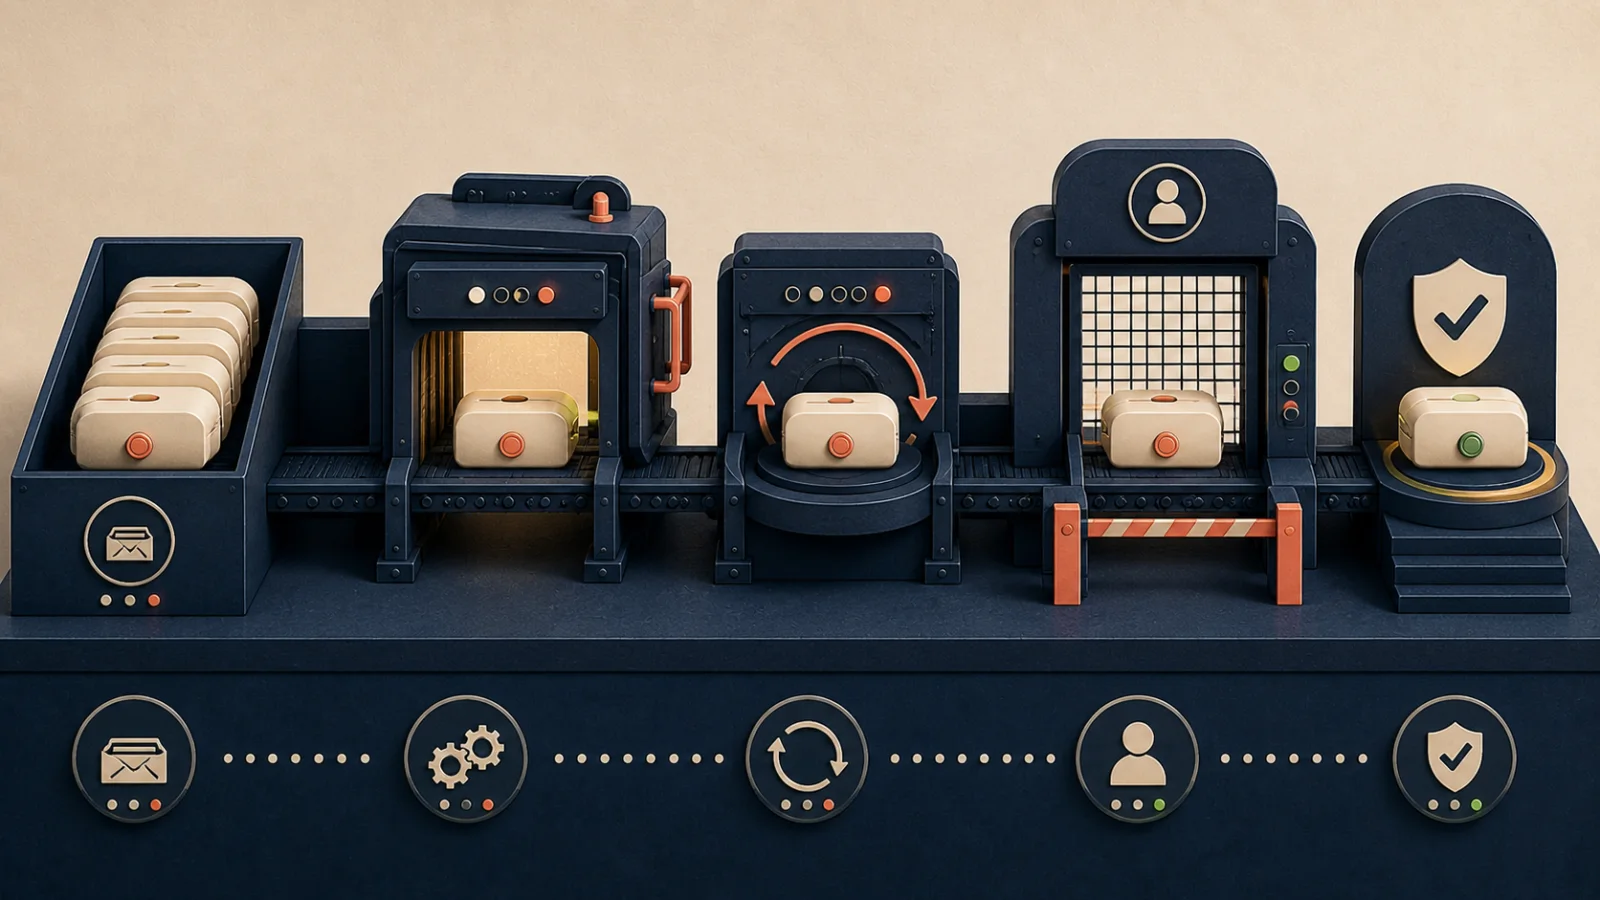
The Timing Problem Is an Architectural Problem
A conventional web request follows a reassuringly simple model: the browser sends data, the server processes it and returns a response. This narrow framework is unsuitable for many AI features. Responses may take a long time, external services may be temporarily unavailable and individual processing steps may need to be repeated. The result may also require validation or human approval.
A longer HTTP timeout does not solve these problems. It merely postpones them. The browser still does not know whether work is continuing, a worker has failed or the connection has simply been interrupted. An endlessly spinning loading indicator implies certainty even though the system itself has none.
The more robust basic assumption is therefore: an AI task is not an extended request, but a business process with its own identity and lifecycle.
This perspective is now also evident in current platform APIs. The OpenAI Responses API supports background execution; webhooks distinguish between completed, failed and cancelled responses, among other states. At the same time, the official documentation notes that background processing affects data retention and is not compatible with every Zero Data Retention configuration. Asynchrony is therefore not merely a performance option, but part of the data protection and operational contract. (OpenAI Webhook Events, OpenAI Data Controls)
A Job Is More Than an Entry in a Queue
Initially, a queue answers only the question of which work should be performed next. A reliable product feature also requires a persistent job model. A useful record contains at least:
- a random job ID that cannot be guessed externally,
- the task type and owner,
- the current state,
- creation, start and completion times,
- the number and timing of attempts,
- a limited, sanitised error description,
- references to the input and result,
- a correlation ID for logs and external calls.
Inputs should not be copied into the job without careful consideration. For personal or security-sensitive data, a reference to the authoritative source is often preferable. The worker then loads only what it needs for the specific step and what the requester is still authorised to access.
Nor does the result necessarily belong directly in the same table. Large texts, images and audio files require their own storage, permission and deletion rules. The job then merely records the traceable relationship between the request and the artefact.
States Instead of Boolean Shortcuts
is_done = 0 is not enough. Between “not yet finished” and “finished” lie several distinct business states. A manageable state model might look like this:
queued → running → succeeded
              ↘ retry_wait → queued
              ↘ failed
queued/running → cancel_requested → cancelled
More complex workflows add states such as waiting_for_input, waiting_for_review or blocked. What matters is not the number of states, but their unambiguous meaning. For every transition, it must be clear:
- Who may trigger it?
- What data is written in the process?
- What does the user see?
- What subsequent work is initiated?
- May the transition be received repeatedly?
This final question is particularly important. Workers may restart after a timeout, webhooks may arrive more than once and network connections may fail immediately after successful processing. A callback is therefore not automatically a new event. Transitions should atomically check whether the job ID, expected initial state and current execution ID match.
This also prevents a subtle error: a delayed result from an old run must not overwrite a restarted job.
At Least Once Means: Possibly Twice
In practice, many queue systems guarantee “at least once” delivery. This is sensible, but it requires idempotency. The same request can be executed again without producing two notifications, duplicate charges or contradictory records.
Several simple patterns have proven effective here:
- Each business request receives a stable idempotency key.
- A worker claims a job through an atomic update or lock.
- External side effects are handled separately from the pure computation.
- The result and subsequent step are linked through a transactional outbox.
- Repeated callbacks confirm the known state instead of triggering it again.
TYPO3 already provides useful foundations for recurring background work. The Scheduler can execute one-off and periodic tasks, prevent parallel executions and log starts, finishes and errors. For new custom tasks, the documentation recommends using Symfony Commands. Although a Scheduler is not a substitute for a business queue, it works well as a controlled timer for workers, clean-up and restarts. (TYPO3 Scheduler 13.4, Scheduler Overview, Custom Scheduler Tasks)
Retrying Is a Business Decision
Not every error deserves another attempt. A useful classification distinguishes at least between:
- temporary errors: rate limits, network interruptions or a temporarily unavailable service;
- permanent technical errors: invalid configuration or an unsupported data format;
- business errors: missing approval, deleted source data or insufficient input;
- quality errors: a formally valid but unacceptable result.
Only the first group can normally be retried automatically using exponential backoff with jitter. The number of attempts needs a fixed upper limit. Otherwise, a defective request creates an infinite loop, consumes budget and obscures its cause.
Business and quality problems, by contrast, require a visible state and often a human decision. “Please add the acceptance criteria” is not a technical fault. The system should not turn it into a fifth identical model call.
This is precisely where a delivery process differs from a chat: the model may determine that it lacks information. A good workflow treats this determination as a valid intermediate result.
The Interface Must Remain Honest
An asynchronous architecture is only complete when the user interface presents its states clearly. After submission, it should immediately display the accepted task with a stable ID. It can then update the status through polling, Server-Sent Events or WebSocket.
The choice of transport is secondary. Clear statements are more important:
- “The task is waiting to be processed.”
- “Processing is in progress.”
- “A temporary error has occurred; the next attempt will be made later.”
- “Information is required before the task can continue.”
- “The task has failed permanently.”
A progress bar is useful only if the process actually has measurable stages. An invented percentage does not make the system more transparent. Named phases such as “Transcribing audio”, “Generating draft” and “Reviewing result” are usually more honest.
Cancellation also requires a defined contract. It may not be possible to stop an external call that is already running immediately. In that case, cancel_requested initially describes the intention. Before causing further side effects, the worker must check again whether the request may still continue.
Two Projects, Two Variants of the Same Principle
In the supplied project information about Vera, AI tasks are processed outside normal HTTP requests. TYPO3 stores jobs, controlled workers execute them and return structured results. For a personal diary application, this is more than a scaling decision: slow responses receive an honest status, retries remain limited and deletion operations must consistently cover long-term memory, media and derived references as well.
AI Development applies the same basic principle to a considerably longer process. There, a Jira task passes through readiness checks, isolated processing, tests, independent evaluation and human acceptance. Missing information, quality errors, merge conflicts and infrastructure problems have separate paths. According to the project description, opaque run IDs prevent delayed callbacks from overwriting a newer run.
These are specific characteristics of these two projects. The resulting general recommendation is not that every application must copy this exact architecture. It is this: as soon as a feature is slow, expensive, repeatable or subject to approval, its lifecycle should be modelled explicitly.
Security Follows the Request, Not the Worker
A background process must not automatically inherit all the permissions of the overall system. The job should specify which resources the particular run may access. Short-lived credentials, minimal tool permissions and separate control and execution environments reduce the consequences of manipulated input or a faulty model result.
Reauthorisation at execution time is equally important. Between a job being queued and started, a user may lose their permissions or delete source data. Permission that existed yesterday is not a permanent mandate.
Explicit approval remains advisable for irreversible or far-reaching steps. Current OWASP guidance for agentic applications likewise emphasises least privilege, clearly authenticated tool access and human review for significant deviations. (OWASP Securing Agentic Applications Guide)
What Must Be Visible in Operation
A production AI workflow does not need the largest possible number of metrics, but operational questions that can be answered:
- How many jobs are waiting, running, failing or require a decision?
- How old is the oldest waiting job?
- Which types of errors occur frequently?
- How long do individual phases take?
- How many retries and external calls are generated?
- Which model, prompt and tool version produced a result?
- Can an operator safely terminate or restart a stuck run?
Logging prompts and model responses wholesale is not a good default solution. Logs should provide states and technical diagnostic information without duplicating personal content or credentials. Hashes, versions, structured result fields and specifically protected audit records may be sufficient for business traceability.
The Real Benefit
A job architecture does not make AI more reliable than the underlying model actually is. It does, however, ensure that uncertainty does not control the entire process. Errors become classifiable, retries can be limited, permissions can be verified and human decisions become visible components of the system.
The most important change therefore takes place in the data model: not “We are still waiting for a response”, but “This process is in a known state”. Once this distinction has been made, the interface, tests, operations and data protection become far more concrete.
A good AI workflow does not promise magic in real time. It shows what is happening, which limits apply and who needs to make the next decision.